An agent that prepares a report can finish in one request. An agent that waits for approval, updates a record, and resumes after an interruption needs a system that can carry the work across those steps.
That system determines much of the experience people have with the agent. Does it remember what was approved? Can it recover without performing the same action twice? Can the team explain why it changed a record?
Those are infrastructure questions. Model quality matters, but putting an agent into a product also means taking responsibility for its state, tools, permissions, and failures. That is what I mean by agents becoming infrastructure.
The model is one part of the system
A language model interprets the context it receives and generates output. An agent combines that capability with a loop that can choose tools, inspect their results, and continue working. The application supplies the product-specific information and controls what those tools can do.
In Engineering in the AI Era, I described the basic pattern as an LLM operating in a loop with tools. To turn that loop into a dependable product feature, several responsibilities need an owner:
- Instructions and context define the job and supply relevant information.
- Tools expose actions such as searching documents or updating a record.
- State and memory preserve progress and information needed later.
- Permissions determine which actions are allowed for a particular user.
- Execution and recovery determine how work runs, pauses, retries, and resumes.
- Observability gives the team a record of what happened.
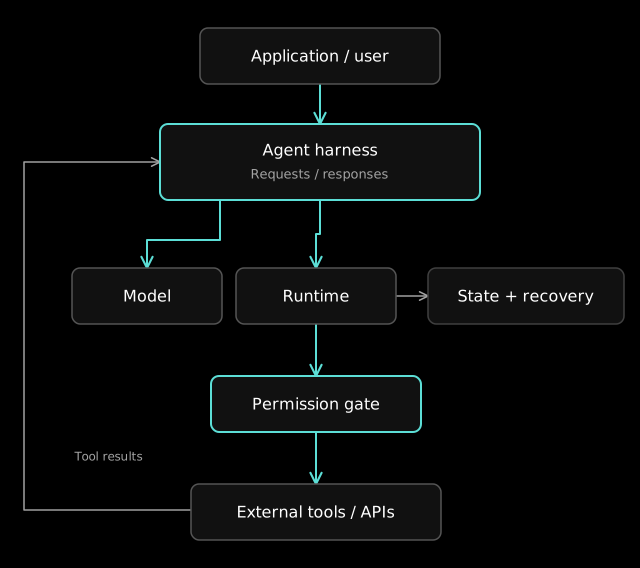
A small feature may handle all of this within an existing application. The important step is to identify the responsibilities before choosing how much infrastructure to add.
Design for the interrupted task
Consider a support agent that can look up an order and prepare a refund request. Looking up the order is a read. Issuing the refund changes the world. Those actions need different controls.
If the workflow requires approval, the system has to retain the proposed action while it waits. When approval arrives, it must verify that the request is still valid and that the approver has the right authority. If the payment provider succeeds but the response times out, retrying blindly could produce a duplicate action.
This example is hypothetical, but the engineering questions are familiar: durable state, authorization, idempotency, and recovery. The model can help choose a next step. The surrounding system must enforce the conditions under which that step runs.
I would begin with the simplest tool loop that satisfies the feature. Persistent execution becomes necessary when the work must survive the request, wait for an event, or resume after a failure. Multiple agents add coordination requirements, so I would introduce them when the work has a useful division of responsibility.
What a managed platform takes on
Managed infrastructure can reduce the amount of runtime and persistence work a team owns. That can make sense when the product's value lies in its workflow and experience, while operating another execution system would consume scarce engineering time.
The distinction between a platform and an SDK matters here. Vercel's AI SDK is a TypeScript toolkit for model integration, tool calling, structured output, and streaming interfaces. Using it doesn't, by itself, settle where the agent runs or how work survives an interruption. Those responsibilities depend on the hosting and persistence you connect around it.
Cloudflare's Agents platform approaches agents as applications with state and lifecycle needs, with support for capabilities such as scheduling, communication, and long-running work. The appeal is having infrastructure primitives available together instead of wiring each one from scratch.
A managed service still leaves product decisions with the team. You define the job, connect authorized tools, decide what data can be retained, and evaluate the resulting behavior. Before adopting one, I would check its recovery semantics and operational limits against an actual workflow.
What you own when you self-host
Self-hosting the agent application gives a team more control over deployment, integrations, state storage, and access to internal systems. That can be valuable when the workflow needs a particular environment or must fit existing operational controls.
It also means owning the service: capacity, upgrades, persistence, failures, monitoring, and the security of tool execution. Running the application yourself doesn't necessarily mean running the model yourself. A self-hosted agent can still call a managed model API.
Frameworks can help organize the application. LangGraph supports stateful orchestration with explicit control over steps and branching. The OpenAI Agents SDK provides building blocks for tools, handoffs, approvals, and tracing. Neither choice removes the need to decide where state lives and who operates the deployment.
I would choose this approach when the additional control serves a concrete requirement and the team can support the operational work it creates.
Choose ownership one layer at a time
Managed and self-hosted are useful labels, but a product can combine them. A team might use a managed model, run its orchestration service in its own environment, store state in an existing database, and expose private business capabilities through narrow APIs.
That makes the choice more practical. Which parts benefit from customization? Which parts are already handled well by infrastructure the team trusts? Where does data need to remain, and what must the team be able to inspect or change?
For a TypeScript application, I would first consider keeping the agent close to the existing authentication, APIs, and interface. Sharing types and operational practices can simplify integration. A Python-heavy data or research system may have different reasons to keep its agent there. The language should fit the surrounding work.
Permissions belong in the system
A prompt can explain that an agent should only access a user's own records. The tool and data layers must enforce that rule.
In the support example, the order lookup should run under an identity with the appropriate access. The refund tool should validate the request and enforce limits. Approval should apply to the specific action presented for review. Logs should connect the request, approval, execution, and outcome so someone can investigate a problem later.
External documents and tool results also need to be treated as data with a source. A sentence inside a retrieved document must not become permission to perform a new action. These boundaries become more important as the agent gains capabilities.
The goal is an agent people can use with confidence because the system makes its authority explicit and its actions inspectable.
Give the agent an owner
Once people rely on an agent, someone needs to maintain its behavior as well as its uptime. That includes the tools it can use, the instructions it follows, the information it retains, and the evaluations used to judge changes.
This is closely related to the work of a forward deployed engineer: understand the real workflow, connect the relevant systems, and stay close enough to the outcome to improve it. The agent's usefulness depends on how well it fits the work around it.
When designing one, I want clear answers about where it runs, what it can change, how it recovers, and who responds when it fails. Those decisions make a capable model into a service a product can depend on.